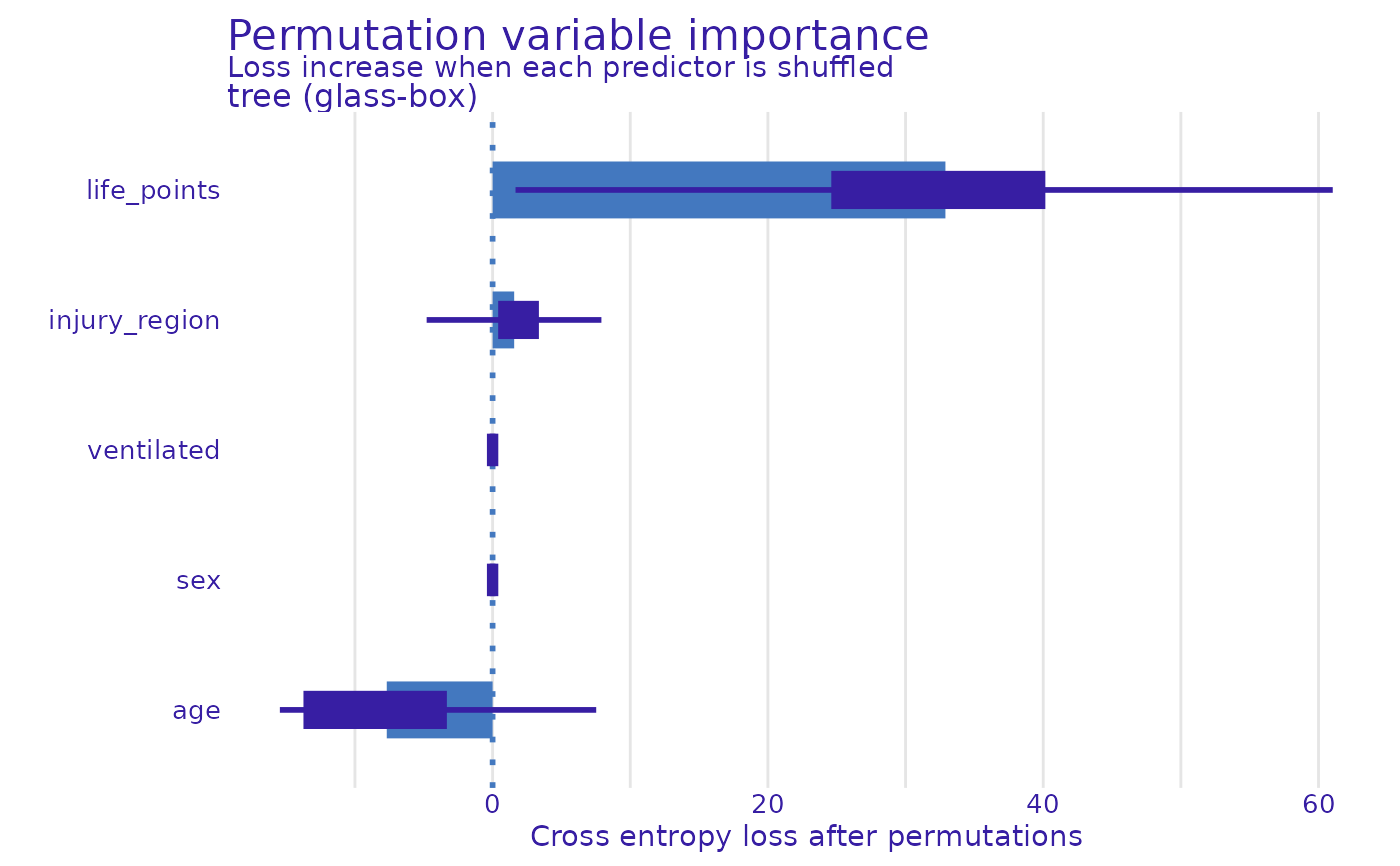
How much worse the model gets when each predictor is shuffled. The measure is model-agnostic, so a random forest and a decision tree are ranked on the same scale.
Arguments
- x
An
sdt_modelfromsdt_fit(), or an explainer fromsdt_explain().- data
Optional data to explain on, passed to
sdt_explain().- n_permutations
Number of permutation rounds. More is steadier and slower.
Examples
co <- sdt_add_decisions(sdt_synthetic_cohort(n = 200, seed = 3), seed = 4)
needed <- c("parsnip", "recipes", "workflows", "rsample", "tune",
            "yardstick", "rpart", "DALEX", "DALEXtra")
if (all(vapply(needed, requireNamespace, logical(1), quietly = TRUE))) {
  fit <- sdt_fit(co, target = "called_triage", engine = "tree",
                 tune = FALSE, seed = 1, verbose = FALSE)
  sdt_importance(fit)
}